What Is a Stale-Version Attack?
A policy changes in March. The new version goes up on the intranet, and the old one is still sitting in a shared drive, in a PDF somebody attached to an email, in last year's export that got synced into the bucket your AI assistant reads from. In June someone asks the assistant about the policy, it finds both pages, and it answers from the old one. The answer quotes a real document, it sounds confident, and nobody notices until somebody who knows the current rule reads it.
That's a stale-version attack. We gave it the name in our arXiv paper on context governance because we needed a word for a test condition: the corpus holds both the current version of a document and a superseded one, and the question is whether the old one reaches the model.
Usually nobody is attacking anything
The name sounds more dramatic than the usual cause. In most companies the old versions get in on their own. Documents get copied, exported, cached, attached, migrated and synced, and every one of those copies is a separate file as far as a search index is concerned. Over time a knowledge base collects a layer of almost-identical pages, some current and some not, and nothing in the pile says which is which.
It also works on purpose. If someone can drop a file into a folder your agents index, they can drop in an outdated version of a page and let the retriever do the rest. I haven't seen that done to a production system, so treat it as a hypothesis, but the mechanism is the same one, and it doesn't need anything clever.
Why the retriever can't tell
Most AI assistants that answer from company documents use some version of RAG, retrieval-augmented generation. The idea is simple. When a question comes in, a search step (the retriever) finds the handful of passages that look most relevant, and those passages get pasted into the model's prompt so it answers from your documents instead of from memory. Whatever the retriever hands over is what the model knows about your business for that answer.
The trouble is that every common way of doing that search ranks by how well a passage matches the question. An old version and a new version of the same page share almost all of their text, so they match almost equally well. Worse, people usually ask about the thing that changed, the new limit or the renamed setting or the deprecated feature, and the old page talks about that thing too, sometimes at more length because it was explaining the old way. Relevance and currency are different properties, and search only measures the first one. Here's how that plays out across the usual pieces.
Keyword search. The oldest approach, usually an algorithm called BM25, scores a passage by which of the question's words it contains and how rare those words are. It's fast, cheap and better than people expect. The old page has the same words as the new one, so it scores about the same.
Vector search. An embedding model turns each passage into a long list of numbers that captures roughly what it means, and the search finds passages whose numbers sit close to the question's. That's how it finds a page that says "terminate" when you asked about "cancel." It's also why it can't tell versions apart: the old page and the new one mean almost the same thing, so they sit almost on top of each other.
Hybrid search. Run both and merge the two ranked lists. It usually beats either one alone on relevance, and it has the same blind spot on currency.
Reranking. A second pass on top of the search. The first pass pulls back a few dozen candidates quickly, then a reranker, a smaller model that reads the question and each candidate passage together, reorders them by how well each one answers the question. It's one of the most effective upgrades you can make to relevance, and it makes this problem worse, because the superseded page often answers the question very well, just with last year's answer. In our test Bedrock's stale rate went from 90% to 95% when we turned the reranker on.
Knowledge graphs (GraphRAG). Instead of only searching text, a model reads every document, pulls out the entities and the relationships between them, and builds a graph you can walk. It's built for questions that need facts from several documents. The facts from the old page get extracted into the graph too, though, and unless someone removes them they sit next to the new ones as equals. Bedrock GraphRAG had fewer stale pages in its results than plain vector search, partly because it returned fewer results, and still gave a stale answer to 16.7% of questions.
Metadata filters. Tag every document with a field like status = current and tell the search to ignore everything else. This one works, and in our test it took Bedrock's stale results to zero. It's only as good as whoever maintains the field, which I'll come back to.
Versioning. Store a changed page as a new version of the same document, so the old text moves into history and only the current version is in the search set at all. This is how ContextNest holds documents, and it's the reason the results below look the way they do.
Why a bigger context window doesn't fix it
The answer I hear most often now is to skip retrieval and stuff everything into the context window. Windows are a million tokens, so put all the docs in and let the model sort it out.
If both versions are in the window, the model is in the same spot the retriever was. It's looking at two confident documents that say different things, and unless one of them happens to carry a date in the text, and the right date, there's nothing telling it which one is current. Stuffing more in makes it more likely the old copies are in there too. There's also research on long contexts, the "Lost in the Middle" paper from Stanford and others in 2023, showing models use information at the start and end of a long context better than information in the middle, so which version wins can come down to where it happened to land in the pile.
And you pay for it. Every token in the window gets billed on every call, so stuffing means paying to send the model the old version along with the new one, over and over. In our arXiv paper the governed approach, which sends only the current approved version, got a higher answer pass rate than keyword retrieval (97% against 90 to 93%) at roughly a third of the input tokens.
The model also brings its own stale version to the table, which is whatever it learned in training. If your context doesn't clearly say what's current, the model's memory of how things used to work is one more old copy in the mix.
Why it matters to the business
What makes this expensive is how a stale answer looks. A hallucination often reads a bit off and someone catches it. A stale answer quotes a real document, with a real title, that used to be true, so it looks just like a good answer and goes straight into the email, the ticket or the decision.
You own the answer. In Moffatt v. Air Canada in 2024, the airline's website chatbot told a customer he could claim a bereavement fare refund after the fact, which contradicted the airline's own policy page. Air Canada argued the chatbot was responsible for its own words, and the tribunal didn't buy it and held the airline to what the chatbot said. As far as I know that wasn't a stale-version case, the chatbot just got it wrong, but it settled the question that matters here. Whatever your assistant tells a customer, you said it.
Agents act on it. An assistant that answers from an old page gives someone a wrong answer. An agent that reads an old runbook, an old price list, an old approval threshold or an old discount policy goes and does the old thing, and it can do it a few hundred times before anyone looks. The more work we hand to agents, the more a stale page turns from a bad answer into a bad action.
You can't show what it read. In regulated work, the question after something goes wrong is which version of the guideline, the SOP or the policy the system used when it made that call. If old and new copies sat side by side in an index, you usually can't reconstruct that. A store that keeps versions as versions can tell you which version was current and which one was served.
People stop trusting it. My hypothesis is that this is the most expensive one and the least measured. Someone catches one confident stale answer, tells their team, and everyone quietly goes back to asking the person who knows. The assistant still gets used for drafting emails, but nobody trusts it with anything that matters, and that's one of the reasons AI gains hit a ceiling outside engineering.
The workaround costs money too. The usual fixes are cleanup projects, a status field someone has to maintain on every document, and a person whose job becomes keeping the index honest. None of that shows up as an AI cost, but it's what you're paying to keep old versions out of the answers.
What it looks like when you measure it
We ran this as part of a larger benchmark of ContextNest against Amazon Bedrock Knowledge Bases. We took 180 pages from the public Kubernetes docs, pulled each one at two points in its git history where a fact had changed, and wrote questions whose correct answer only exists in the new page. After an audit that threw out questions where the change didn't really matter, 278 were left.
Both versions went into Bedrock the way they'd sit in most document stores. The same pages went into a ContextNest vault as one document with version history, where only the current published version is searchable. Same embedder on both sides, same reranker, same budget.
- Bedrock had the superseded page in its top 10 results for 90% of questions. With the reranker on, 95%.
- With Claude Sonnet 4.6 writing answers from what each system retrieved, Bedrock with rerank gave a stale answer to 17.4% of questions, about one in six. ContextNest gave a stale answer to 0.8%.
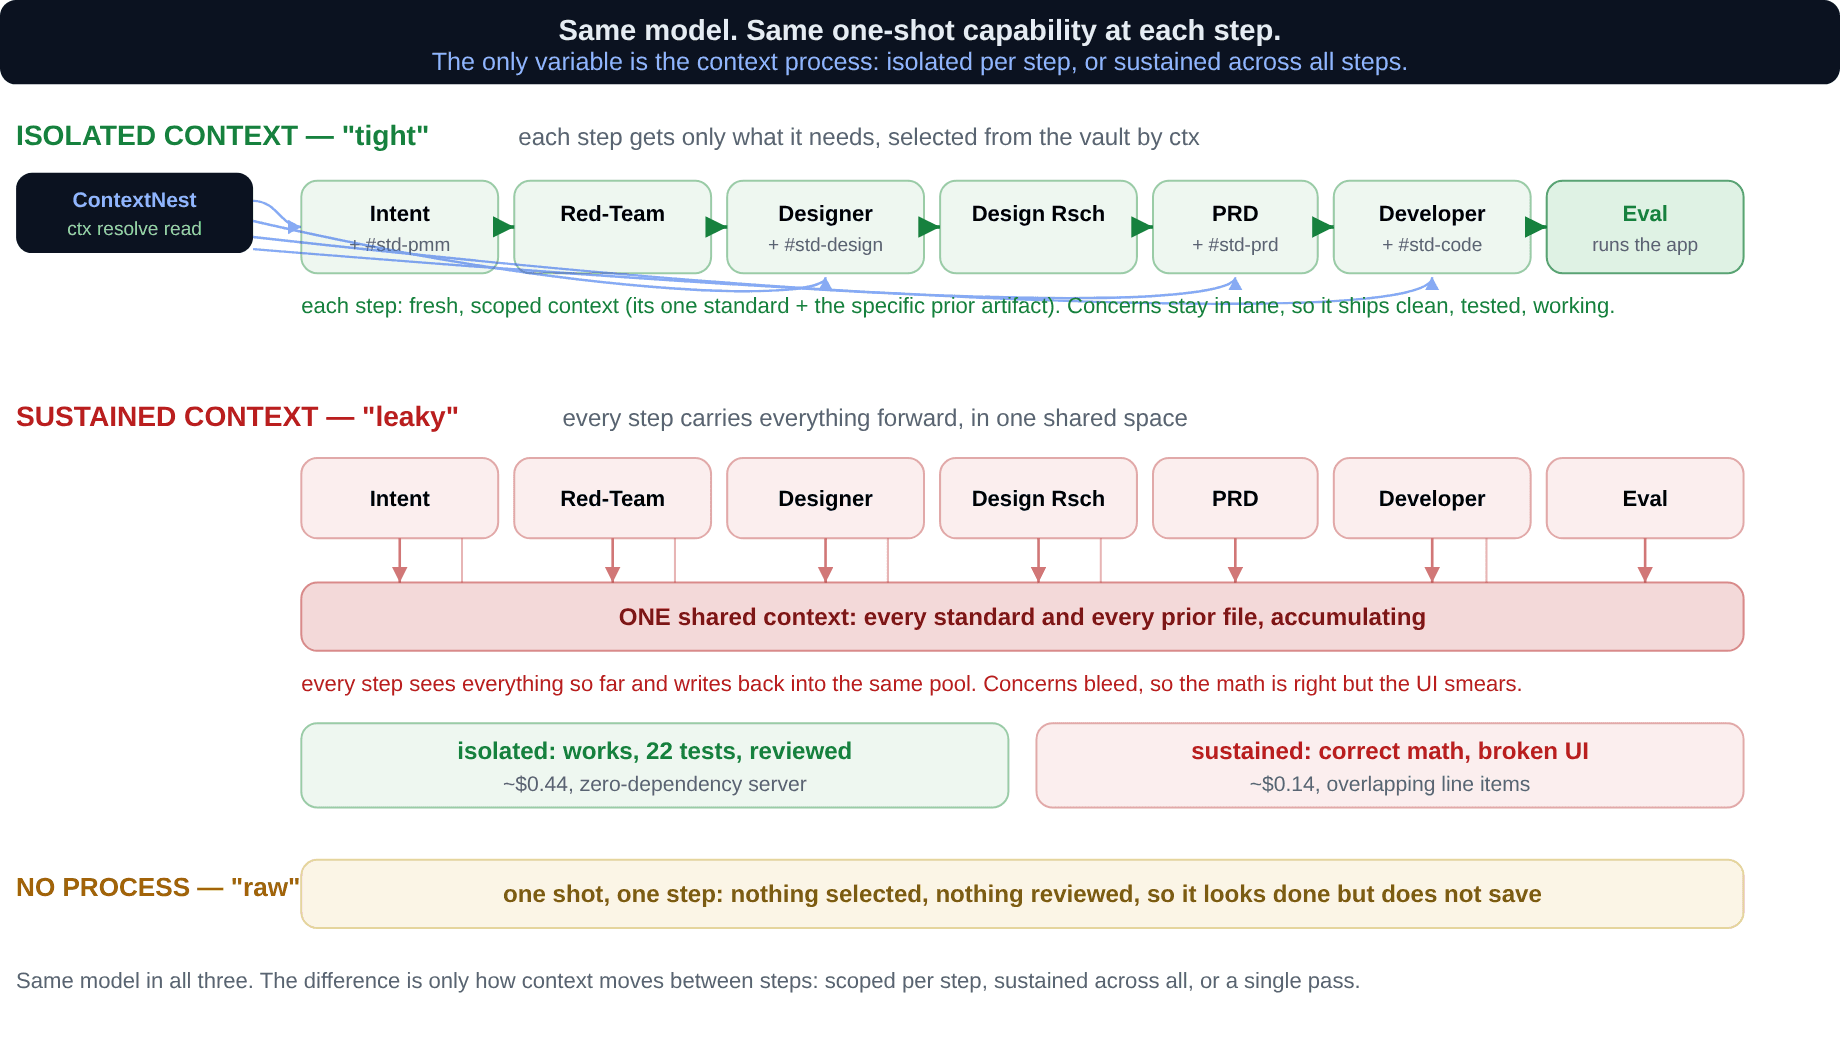
- When we loaded the old copies into ContextNest as plain separate files, with no versioning, it leaked just like Bedrock did, 91%. Same engine, same ranking. The only thing that changed was whether the old text was a superseded version or just another document.
That last result is the one I'd pay attention to. What fixed it in our test was a store that knows the difference between an old version of a page and a different page.
The full write-up, with every table, the losses, the cost ledger and the protocol amendments, is here: ContextNest vs Amazon Bedrock, benchmark v3.1.
Three ways to defend against it
Delete the old copies. It works if you can find them all, and you lose the history, which matters the day someone asks what the policy said when a decision was made.
Tag and filter. Put a status field on every document and filter to current. In our test a Bedrock metadata filter took stale results to zero, so this works. The catch is that someone has to set that field on every document, forever, and the day the pipeline that sets it breaks, you're back to one in six without any error to tell you.
Keep versions as versions. Store a changed page as a new version of the same document, so the old text moves into history instead of sitting in the search set. This is what ContextNest does, and it's why the versioned arms in our benchmark scored zero. The old version is still there if you ask for it by version, it just never competes with the current one.
Try it on your own corpus
You don't need our setup to find out whether you have this problem. Pick 20 documents that changed in the last year, write one question each about the fact that changed, and run them through whatever your agents use. Count how many times the old version shows up in the results, and how many answers come back with the old fact. It's an afternoon.
My hypothesis is that most teams running AI on their own documents have a stale rate they've never measured, and that it's higher than anyone on the team would guess. If you run the 20-question test I'd like to hear what number you get, whichever way it goes.
ContextNest is open source and installs from npm: @promptowl/contextnest-cli
Get insights like this delivered
Join leaders navigating AI governance and agentic systems.